Training data
ToothFairyAI allows you to manage the datasets needed to train your AI models. This document provides an overview of the training data creation and import process.
Menu location
Training data can be accessed from the following menu:
Training data > Create new doc
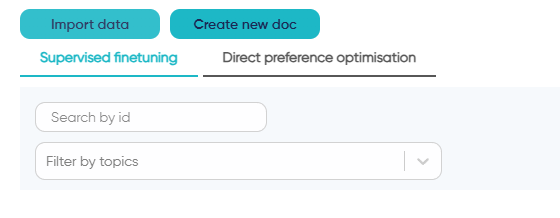
All training documents are managed in a single table — there are no separate tabs per method. Every document carries a type (shown in the Type column, filterable via the All types dropdown):
- Conversations (
conversationalTraining): conversational (instruction–answer) datasets for supervised finetuning - Preferences (
generativeTraining): preferred vs non-preferred response datasets for direct preference optimisation - RL tasks (
rlTask): task definitions (a prompt plus a programmatic checker) for RL with verifiable rewards
ToothFairyAI supports six training methods (training_type), but there are only three document types, because several methods draw from the same kind of document:
| Document type | Methods that draw from it |
|---|---|
Conversations (conversationalTraining) | conversationalTraining (SFT), grpoTraining (GRPO), continuedPretraining (CPT) |
Preferences (generativeTraining) | generativeTraining (DPO), ktoTraining (KTO) |
RL tasks (rlTask) | rlTask (RLVR — reinforcement learning with verifiable rewards, runs on the GRPO engine) |
See the Fine-tuning overview for the full method comparison and the Managed fine-tuning reference for the parameters each method accepts.
There is no synthetic instruction–answer generation pipeline. A training dataset is built from data you create or import:
- Authored in the platform as
Live documentswith structured snippets (this section), and/or - Imported as JSONL files (next section).
When you start a job, the /finetuning/dataset step fetches those documents for the selected topics and training_type, converts them into the JSONL shape the chosen method expects (conversations for SFT/GRPO/CPT, preferences for DPO/KTO, task manifests for RLVR, plain text for CPT, image+text for VLM), splits into train/test, and uploads the result to S3. Your documents are transformed, not generated — nothing new is invented, so the dataset is exactly as good as the data you put in.
Creation of training data
The creation of the training data is ultimately comes down to the creation of a Live document with a specific structure.
As for the Knowledge Hub live documents, users can collaborate in real time to create the training data needed to fine-tune the AI models.
The fantastic feature of this approach is that the training data is a blend between real documents and structure embedded snippets aware of the content surrounding them.
The behaviour of the Live document is very similar to the Knowledge Hub live documents, with the following differences:
General fields
- Topics: The topics are used to filter the training data. The user can select the topics that are relevant to the training data
- Validation: It sets whether the document and the training data is used for fine-tuning the AI model or solely for validation purposes
- Add snippet: Conversational AI will show
ADD SYSandADD TURN. RL tasks will showADD SYS,ADD RL TASKandADD RL CHECKER.
The ADD SYS button allows the user to inject a system message into the document as an initial block right under the title of the document. The system block is by all means optional however we do recommend including it if the downstream model you want to generate via finetuning requires a strong agentic behaviour.
The ADD TURN button allows the user to add a new training snippet. More details below.
Conversational snippets (Conversations documents)
The conversational AI snippet consists of the following fields:
- Role: The selection of the role of the AI model in the conversation. The user can select from the following roles:
- System: To inject a system message into the conversation
- User: To inject a user message into the conversation
- Assistant: To inject an assistant message into the conversation
- Message: It is highly recommended to alternate strictly between the user and the assistant messages and finish the conversation with the assistant message.
Preference snippets (Preferences documents)
The direct preference optimisation snippet consists for the most part of the same fields as the supervised training snippets.
In essence, the direct preference optimisation snippets are by all means identical to the supervised training snippets covered above with the addition of a DPO dedicated snippet.
The DPO snippet is used to specify the preferred and non-preferred assistant messages at the end of the conversation.
By default the role of the DPO dedicated snippet is Assistant and the preferred and non-preferred assistant messages must be specified to be able to create the DPO dataset.
Incomplete conversations will not be accepted in training data creation step for DPO.
RL task snippets
An RL task document is authored with two dedicated snippets instead of conversational turns. The editor toolbar shows ADD RL TASK and ADD RL CHECKER (one of each per document); the optional ADD SYS injects a system premise for the task.
- RL Task: defines what the agent must accomplish.
- Task prompt: The instruction shown to the agent (required).
- Environment: The sandbox the task runs in —
tfcode(the only environment in v1). - Max tool calls: The tool-call budget per episode (1–64, default 16).
- Setup commands: Optional shell commands run before the episode (one per line).
- RL Checker: defines how success is verified — the reward comes only from what the checker can prove, never from the model's own text.
- Checker type:
Exit code,File exists,Pytest, orScript. - Checker config: Type-specific fields (e.g. the command to run and expected exit code for
Exit code).
- Checker type:
See the RL with Verifiable Rewards page for the full task_spec reference, the four checkers and reward-design guidance.
Training data generation
The editor content outside the snippets is not used for the chat training data; however it can be used to provide additional information to the user reviewing the chat training data.
The user can delete the snippet by clicking on the Delete icon on the top right hand side of snippet
ToothFairyAI enforces the alternation between user and assistant roles at the time of the creation of the training data; this manifests in a semi-empty message with the appropriate role in between two consecutive snippets with the same role. We highly recommend to avoid these edge cases as they can significantly impact the quality of the dataset down the line.
Import of training data
ToothFairyAI allows you import data in the form of JSONL files that natively support the structure required by the AI models and blend with the data created in the platform through the Live documents.
File size limits per subscription:
- Serverless: Maximum 20MB per file
- Enterprise: Maximum 20MB per file
Conversations (SFT / GRPO / CPT) training data
The import of the training data is done by uploading a JSONL file. ToothFairyAI will not validate the content of the JSONL file, so it is important to ensure that the JSONL file is correctly formatted.
Each line of the JSONL file must strictly contain a JSON object with the following structure:
{
   "messages": [
    {
      "role" : "system",
      "content" : "System message"
    },
    {
        "role": "user",
        "content": "User message"
    },
    {
        "role": "assistant",
        "content": "Assistant message"
    },
    ...
  ]
}
Preferences (DPO / KTO) training data
The import of the training data is done by uploading a JSONL file. ToothFairyAI will not validate the content of the JSONL file, so it is important to ensure that the JSONL file is correctly formatted.
Each line of the JSONL file must strictly contain a JSON object with the following structure:
{
   "input": {
      "messages": [
          {
            "role" : "system",
            "content" : "System message"
          },
          {
              "role": "user",
              "content": "User message"
          },
          {
              "role": "assistant",
              "content": "Assistant message"
          },
          ...
        ]
   },
   "preferred_output": [
    {
      "role": "assistant",
      "content": "Assistant message"
    }
  ],
  "non_preferred_output": [
    {
      "role": "assistant",
      "content": "Assistant message (non preferred)"
    }
  ]
}
RL task (RLVR) training data
RL tasks are imported as a JSONL file where each line carries a single task_spec object. Select the RL tasks type in the import wizard. Each line must strictly contain:
{
  "task_spec": {
    "prompt": "Create a file named hello.txt containing exactly: Hello World",
    "env": "tfcode",
    "max_steps": 16,
    "system_message": "Optional premise for the task",
    "checker": {
      "type": "exit_code",
      "config": { "command": "grep -q 'Hello World' hello.txt", "expected_code": 0 }
    }
  }
}
| Field | Required | Description |
|---|---|---|
task_spec.prompt | yes | The instruction shown to the agent |
task_spec.env | no | Rollout environment — tfcode only (default) |
task_spec.max_steps | no | Tool-call budget per episode (1–64, default 16) |
task_spec.system_message | no | Optional premise injected as the system message |
task_spec.setup_files | no | Object of { relativePath: contents } pre-seeded before the episode |
task_spec.setup_commands | no | Array of shell commands run before the episode |
task_spec.checker | yes | { type, config } — the verifier that produces the reward |
The import wizard validates each line before upload: prompt must be a non-empty string, env must be tfcode, max_steps an integer in 1–64, checker.type one of pytest | exit_code | file_exists | script, and checker.config must carry the fields the chosen type requires (test_paths for pytest, command for exit_code, paths for file_exists, script for script). See the RL with Verifiable Rewards page for the checker semantics and reward-design guidance.
ToothFairyAI validates the JSONL structure at upload time and reports the offending lines in the import wizard. Errors raised later during the finetuning process itself (for example a checker command that cannot run in the sandbox) surface on the Fine-tuning job in status InError.